Aktualisiert am
Das Wichtigste in Kürze
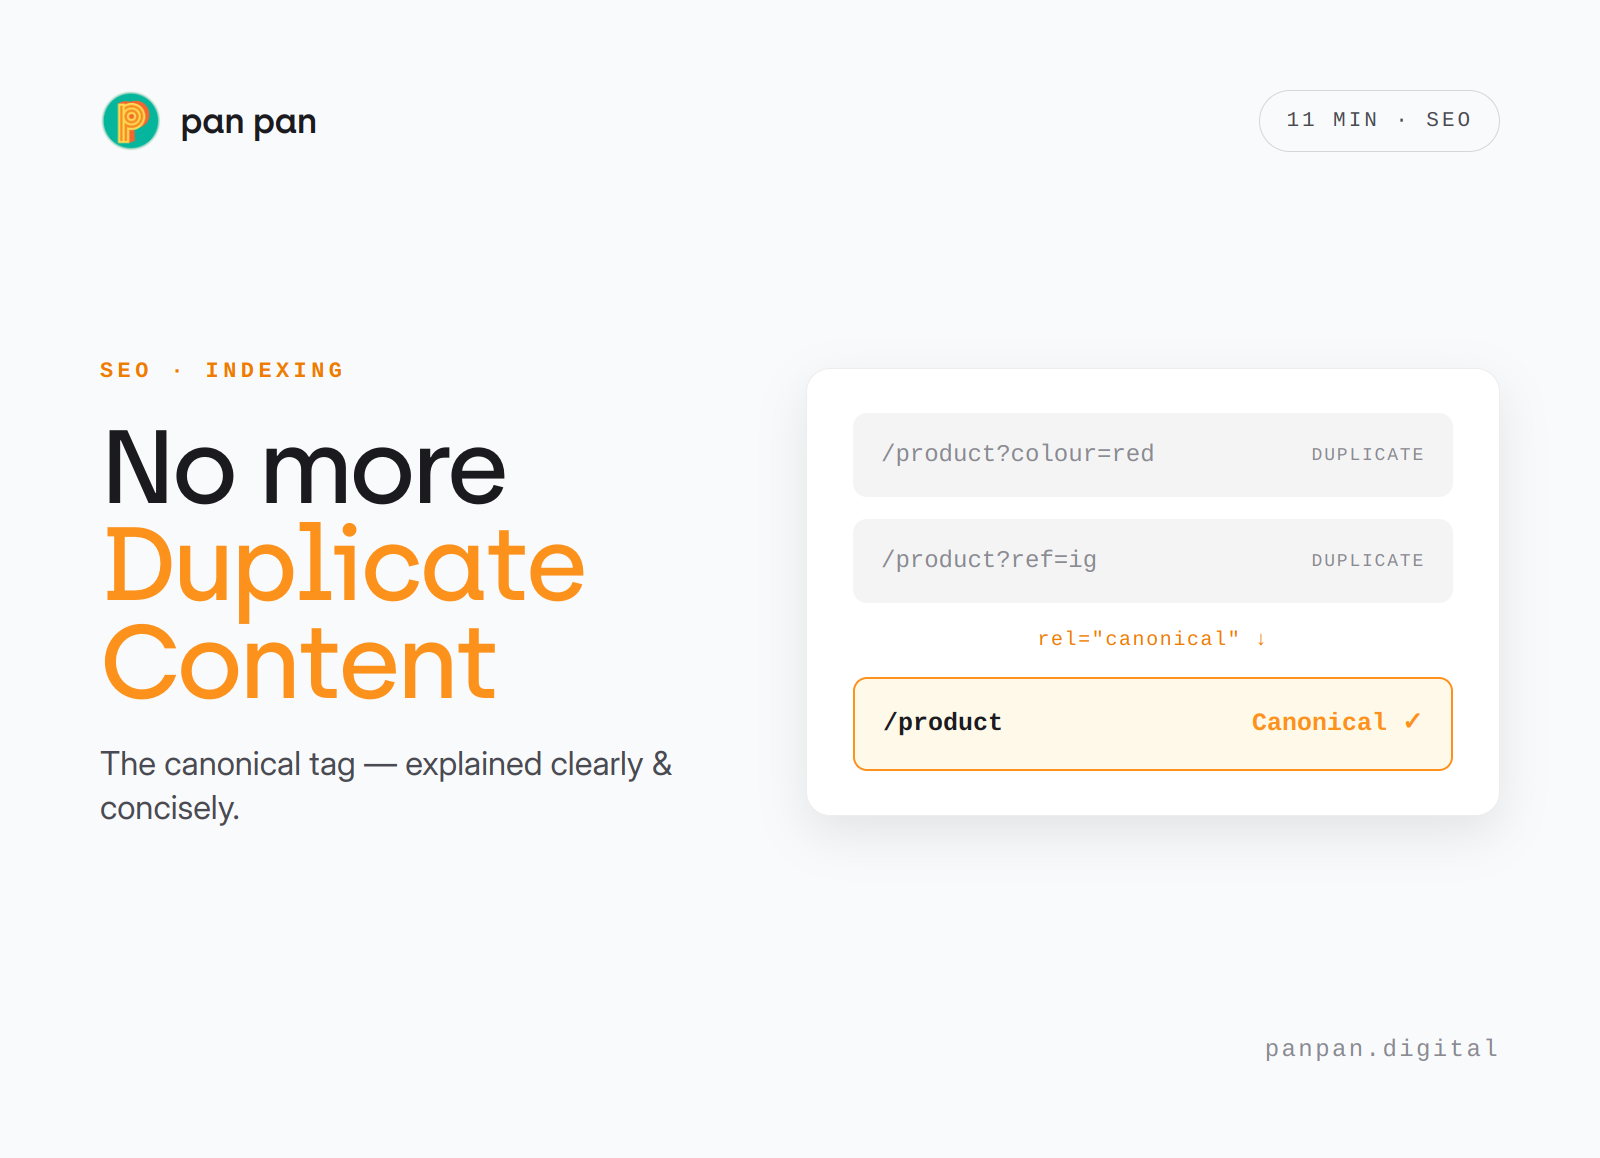
The canonical tag tells search engines which URL is the preferred version of a page when several URLs show identical or very similar content. It consolidates ranking signals, saves crawl budget and prevents the wrong page from ranking. Typical use cases are product variants, filter pages and tracking parameters. Important: Google treats the canonical as a hint, not a directive – conflicting signals lead to it being ignored.
Auf einen Blick
The canonical tag (also called rel=canonical) is a small HTML snippet in the <head> section of a web page that gives search engines a clear recommendation as to which URL should be treated as the preferred version of a page. In practice, it is mainly used to avoid duplicate content – identical or very similar content on different URLs. Why does that matter? Duplicate content can confuse search engines, bloat the index unnecessarily and, in the worst case, lead to the wrong page appearing in the search results. Studies show that almost 30 % of all content on the web is duplicate content (source: Raven Tools) – a huge amount that underlines the need for effective solutions.
Google, Bing and other search engines introduced the canonical tag back in 2009 to give website owners a tool against duplicate content. SEO managers, marketing leads and shop owners run into the topic all the time: for technical reasons, similar or identical content can quickly end up on a website several times over. This is where the canonical tag comes in to create clarity for search engines. It signals: “Hey Google, this is the main page – please index this one!” In doing so, the canonical tag helps save crawl budget, consolidate ranking signals and ensure the best possible user journey.
Before we get into the details: the canonical tag isn't rocket science, but it is an essential standard in modern SEO – especially for larger online shops and content websites. In this guide you'll learn everything you need to know, from typical use cases and common mistakes to best practices, tools and strategic tricks. Let's get started!
When do you use a canonical tag? Whenever several URLs show very similar content. Here are some typical use cases from practice (from e-commerce to B2B):
In short: wherever the same or very similar content appears at several addresses, the canonical tag is worth its weight in gold. It protects you against cannibalising your own content and makes sure that only the most relevant version ends up in Google's index.
As useful as the canonical tag is, as SEO consultants we unfortunately see plenty of implementation errors and misunderstandings in practice. Here are the most common pitfalls so you can avoid them in your project:
As you can see, the devil is in the detail. Many of these mistakes are technical, others come from wrong assumptions. Fortunately, you can avoid all of them once you know about them – which is exactly why you're reading this guide!
Now that we know what can go wrong, the question is: how do you get it right? Here are best practices for working with canonical tags – plus tools to check and monitor your implementation.
Every indexable page gets a self-referencing canonical: It's good practice to give every important page a canonical tag pointing to itself if the page should be indexed under its own URL. Example: the homepage contains <link rel="canonical" href="https://www.example.com/">. A self-canonical like this creates clarity: if duplicates of the page are ever created by accident, Google knows immediately which URL is the right one. Modern CMSs often set self-referencing canonicals by default – but you should still check.
Point duplicates consistently to the main URL: Whenever there's duplicate content (see the use cases above), one version should always be defined as canonical, and all other duplicate URLs point to this master version via the canonical tag. For product variants, for example, every size/colour URL points to product.html without parameters. Important: the canonical page itself points to itself (see above). That creates a clean canonical structure without breaks.
Use absolute URLs in the canonical: The href in the canonical tag should ideally be a full URL (including https://). Relative paths can work in theory, but they increase the risk of errors. Consistent use of www or non-www, trailing slashes etc. is also part of a consistent strategy – the canonical URL should look exactly like the URL you want indexed.
Don't canonicalise paginated pages to page 1 (unless it makes sense): With pagination (e.g. page 2 of an article list), don't simply canonicalise every page to page 1. In the past, rel="prev/next" was used for this, but Google no longer supports it. The best approach is usually to keep all pages indexable – Google recognises paginated pages as belonging together, provided they have value of their own. A canonical can be an option if pages 2 to N have very thin content and you explicitly only want page 1 to rank, but that's an advanced case that requires care.
Combining with hreflang: For multilingual websites, don't merge different language versions via canonical (unless they are 1:1 duplicates in the same language). Use hreflang instead to tell Google about your language and country variants. A canonical only comes into play here if one language version is preferred and the other is genuinely redundant (e.g. identical English content on .com and .co.uk – you could canonicalise one to the other, although taking one version offline would be cleaner).
Run regular audits: Websites are constantly changing – updates, new features or team changes can quietly undermine your canonical strategy. So schedule regular SEO audits to check your canonical tags, and pay particular attention to correct canonicals during relaunches.
Google Search Console (GSC): The most important tool for checking canonicals is the free Google Search Console. Under “Indexing” → “Pages” you can see which URLs have been indexed and whether Google reports “Alternate page with proper canonical tag”. You'll also see if Google has chosen a different canonical than the one you specified – a clear sign that something needs fixing. With URL Inspection, you can check which URL Google considers canonical for a specific page. A quick look at GSC also reveals issues such as duplicate canonicals, ignored canonicals or pages wrongly marked as duplicates. Tip: check in regularly – a few minutes can give you a lot of insight.
Screaming Frog & other crawlers: If you want to dig deeper or have a large website, crawlers like Screaming Frog SEO Spider are invaluable. You can crawl your website and export every canonical tag page by page. This lets you spot pages without a canonical, canonicals pointing nowhere, or canonical chains. You can also check whether two pages accidentally canonicalise to each other (it happens, and it causes confusion). Screaming Frog also offers reports such as a list of all canonical links and their targets – ideal for checking consistency.
Browser tools and extensions: For quick checks of individual pages, your browser is often enough. Right-click and choose “View page source” (or better, use Inspect in Chrome to see the rendered result in case JavaScript changes the canonical) and search the HTML for <link rel="canonical">. There are also handy SEO browser extensions (for Chrome, e.g. “SEO META in 1 CLICK” or “Ayima Redirect Path”) that show you at the click of a button whether a canonical is present and where it points. That way you can keep an eye on it while browsing your website.
Other monitoring tools: Many comprehensive SEO tools (such as Semrush Site Audit, Ahrefs or Sitebulb) have modules that detect duplicate content and check canonical tags. Log file analysis can also be revealing: if Google keeps crawling certain URLs despite a canonical, it's worth checking whether the canonical is implemented correctly.
In summary: with the right tools, you keep track and make sure your canonical tags work as intended. If in doubt, it can be worth having an SEO expert take a look – wrong canonicals can cost you visible traffic, while correct canonicals ensure clean indexing and full SEO power.
Canonical tags can be used not only within a website but also strategically on a larger scale. Two scenarios stand out: cross-domain canonicals and their use during website changes or relaunches. Let's take a look:
Cross-domain canonicals: Normally, canonical tags point to URLs on the same website. But you can also point to a different domain – this is called a cross-domain canonical. When does that make sense? Imagine a company running two websites with very similar content – for example an old shop and, in parallel, a new shop on another domain that is being built up step by step. The goal is to steer Google towards the new shop without switching off the old one right away. In this case, important pages of the old shop can get a canonical tag pointing to the corresponding page on the new domain. This tells Google: “For this product/category, please prefer the new domain.” This tactic can help build up the new domain's rankings faster, because Google doesn't treat the content as competing duplicates but considers the new shop the authoritative version. Important: both pages must be almost identical, otherwise Google may ignore the canonicals. Cross-domain canonicals can also be used for content syndication – e.g. when a blog post is republished on a partner website, the partner page can point to the original via canonical to avoid duplicate content and attribute rankings to the original.
SEO during relaunches: For domain changes or major relaunches, 301 redirects are usually used to forward old URLs to new ones – that's the cleanest solution. But there are cases where canonicals are used temporarily. Example: a company wants to migrate content to a new domain step by step without redirecting right away, because the old website still needs to be live. A cross-domain canonical (as described above) is then an interim solution. But it shouldn't stay that way forever – in the long run, redirects or switching off the duplicate website are the better way to create consistency. Still, in strategic SEO planning, a canonical can serve as a gentle nudge in the right direction where hard redirects aren't (yet) possible.
Link equity and ranking signals: A frequently discussed question is to what extent a canonical tag passes on ranking signals. Background: if page A and page B are identical and A points to B via canonical, backlink signals are usually consolidated as well – in other words, all external links to A ultimately benefit B (similar to a 301 redirect). Google itself introduced canonicals as a signal for consolidating links, and older SEO articles also described the canonical as a way to pass on “link juice”. Today you can put it simply: a canonical consolidates signals and prevents two pages from competing for rankings in parallel. In that sense, it indirectly strengthens the chosen canonical page. However, it doesn't fully replace a redirect if the goal is to send all users and links to a new URL for good.
Be careful with different content: Only set canonical tags if the content really is the same or very similar. It would be a strategic mistake to point a weaker page to a stronger page with different content via canonical, just in the hope of a ranking boost. Google recognises these games and will ignore the canonical – or, in the worst case, rate both pages lower because trust drops. Example: you can't point a blog article to your homepage via canonical in the hope that the homepage will then rank for everything. Use canonicals strategically – don't misuse them!
In summary: canonicals are flexible tools in the SEO toolbox. Used wisely, they help you stay in control of complex setups (multiple domains, gradual migrations, duplicate content from partnerships) – as long as it stays logical for Google. If you're unsure whether a cross-domain canonical is appropriate, ask an experienced SEO. There are often several solutions (redirect, noindex, canonical), and which one is strategically best depends on the individual case.
The canonical tag is an HTML link element placed in the head of an HTML page. It points search engines to the original URL (also called the canonical URL) – the preferred version of a piece of content. Website owners use the canonical tag to avoid duplicate content, signal the correct version to search engines and concentrate organic traffic on the relevant page.
The canonical tag goes inside the <head> section of an HTML document. It's a link element with the attribute rel="canonical" and an href attribute containing the full canonical URL (starting with https). Alternatively, canonicalisation can be done via the HTTP response header – useful for non-HTML documents such as PDFs or other file types that can't contain an HTML tag.
A 301 redirect automatically sends users and search engines from one URL to another and permanently passes on rankings and traffic. A canonical tag, on the other hand, is a link element that only recommends to search engines which version of a page should be treated as the original URL. In other words, users don't notice canonicals – they stay on the page they called up. Redirects are more binding than canonicals, but canonicals offer more flexibility when consolidating similar HTML pages or documents such as PDFs.
That depends on the type of duplicate content. A noindex tag clearly tells search engines not to include a page in the index at all. A canonical tag, by contrast, points to the preferred “canonical URL” of a similar page. For content that offers little value on its own (e.g. print versions, internal search results or comment pages), noindex is often the right choice. Pages that are similar but still important (e.g. product variants) are typically canonicalised to a shared original URL.
Yes, a canonical tag can point to an original URL on another domain. This is called a cross-domain canonical and is used, for example, when the same content or documents (such as PDFs) exist on several domains. The important thing is that both pages are almost identical in content. Alternatively, you can set the canonical via the HTTP response header, especially if there's no classic HTML document.
Google treats the canonical tag as a recommendation, not a requirement. If Google ignores it, the canonical URL may differ significantly in content from the page pointing to it. Faulty implementation in the page's head, conflicting signals (e.g. combined with noindex) or incorrect canonicalisation can also be the reason. Check the implementation in both the HTML and the HTTP response header to make sure Google accepts your canonical.
The canonical tag is a small measure with a big impact. Used correctly, it creates clarity: your most important pages appear in the index, while duplicates stay in the background. As websites become larger and technically more complex, the canonical tag is a must-have for every SEO manager and webmaster. Still, it's no cure-all – careful implementation and regular monitoring are essential so that Google follows the hint as intended.
At pan pan, we offer SEO consulting and digital strategy consulting to help you develop the right SEO strategy. Get in touch to learn how we can help your brand grow in organic search.